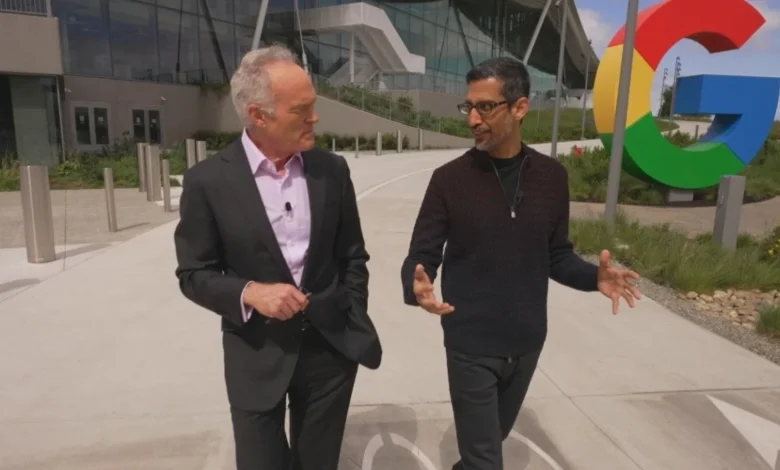
The intersection of artificial intelligence, corporate public relations, and mainstream media reporting has come under intense scrutiny following a recent segment on CBS’s 60 Minutes. The report, which featured Google CEO Sundar Pichai and Vice President James Manyika, claimed that Google’s AI technology had independently acquired the ability to translate Bengali—a language the segment suggested the model had never been taught. However, the narrative has been met with immediate and sharp pushback from prominent AI researchers, who argue that the network and the tech giant conflated basic machine learning functionality with "emergent" autonomous intelligence.
The controversy centers on the capabilities of PaLM (Pathways Language Model), the underlying architecture that powers Google’s Bard chatbot. During the broadcast, correspondent Scott Pelley posited that the AI had "learned a language it had never seen before all by itself," framing the software as a mysterious "black box" that operates beyond the comprehension of its own creators. This portrayal of "emergent properties"—a term used in the tech industry to describe unexpected skills arising from complex models—has ignited a debate about whether such terminology is being used to shroud standard technical processes in an aura of mystical, near-human capability.
A Chronology of the Claims and Disclosures
To understand the scope of the disagreement, one must look at the technical documentation provided by Google itself. The claim that the model learned Bengali spontaneously is contradicted by the company’s own research papers. In the official documentation for PaLM, released by Google researchers in 2022, it is explicitly stated that the model was trained on a dataset that included Bengali text, which accounted for approximately 0.026% of the total training corpus.
The timeline of Google’s public demonstration of this technology began in mid-2022 at the company’s annual I/O developer conference. During that event, Sundar Pichai showcased PaLM’s ability to interact in Bengali. At the time, the focus was on the model’s ability to synthesize information without having been explicitly trained on "parallel sentences"—paired translations—between English and Bengali.
The 60 Minutes segment, however, escalated this technical achievement into a narrative of autonomous acquisition. By suggesting the model had "adapted on its own" to a language it had not been trained to know, the program provided a narrative that experts say is fundamentally misleading. When the segment aired this past Sunday, the reaction from the scientific community was immediate, with researchers utilizing platforms like Twitter to provide the context that the television report omitted.
Technical Analysis: What Prompting Actually Is
The core of the dispute lies in the misunderstanding of how large language models (LLMs) function. Margaret Mitchell, a former co-lead of Google’s AI ethics team and a current researcher at Hugging Face, was among the first to challenge the segment. She emphasized that LLMs are statistical engines that predict the next token in a sequence based on the data they have already ingested.
"By prompting a model trained on Bengali with Bengali, it will quite easily slide into what it knows of Bengali," Mitchell explained. She noted that it is technically impossible for a model to speak a language it has never accessed during its training phase. The process demonstrated by 60 Minutes—asking a model a question in a language that exists within its training data—is simply the definition of how these systems are designed to operate.
This distinction is crucial for the public understanding of AI. If the audience believes an AI is "learning" in the same way a human child learns a new language through observation, they are more likely to ascribe consciousness or agency to the machine. Conversely, if the public understands that the AI is simply retrieving and organizing statistical associations from a vast, pre-existing dataset, the perception of "magic" or "sentience" dissipates.
Official Responses and the PR Strategy
When reached for comment, Google spokesperson Jason Post provided a clarification that attempted to bridge the gap between the company’s marketing narrative and the technical reality. According to Post, the company never asserted that the model was devoid of Bengali training data.
"While the PaLM model was trained on basic sentence completion in a wide variety of languages (including English and Bengali), it was not trained to know how to translate between languages, answer questions in Q&A format, or translate information across languages while answering questions," Post stated. He argued that the "emergent" capability was the ability to perform these specific tasks—translation and Q&A—without having been explicitly coached on them through fine-tuning.
While this may be a valid distinction in the field of machine learning research, critics like Emily M. Bender, a linguistics professor at the University of Washington, argue that it is a distinction without a difference in terms of the "black box" narrative. Bender took particular issue with James Manyika’s claim that the model could now "translate all of Bengali." She labeled this an "unscoped, unsubstantiated claim," questioning the testing parameters and suggesting that such language is designed to inflate the perceived power of the technology.
The Broader Implications of "Emergent Properties"
The use of the term "emergent properties" has become a point of contention among AI ethicists. Dr. Bender has suggested that the term is increasingly used as a proxy for "Artificial General Intelligence" (AGI)—a hypothetical, sentient, or near-sentient system that can outperform humans in all intellectual tasks. By framing AI as something that "just happens" or "emerges" from the code, corporations may be attempting to evade accountability for the limitations, biases, and hallucinations inherent in their products.
The implications of this rhetoric are twofold. First, it creates a "magic" narrative that can lead to excessive investment and hype, potentially blinding stakeholders to the very real safety and ethical risks associated with deploying these models. Second, it shifts the responsibility away from the developers. If the behavior is "emergent" and "not well understood," then the company can effectively argue that they are not responsible for the model’s outputs, as they did not "program" those behaviors directly.
Industry observers note that this strategy serves the corporate goal of appearing at the cutting edge of a technological revolution. By positioning AI as an unstoppable force of nature that is rapidly evolving beyond its original constraints, companies like Google can maintain a competitive edge in the market while keeping regulators and the public in a state of awe.
Transparency and the Media’s Role
The failure of 60 Minutes to verify the claims made by Google representatives highlights a growing concern regarding how mainstream media covers the AI sector. Journalism in this space requires a high degree of technical literacy, as the nuances between "statistical prediction" and "autonomous learning" are massive. When networks fail to bridge this gap, they risk becoming a megaphone for corporate public relations rather than a source of objective information.
As of the time of writing, CBS has not provided a formal response regarding the accuracy of the segment. However, the pressure on major tech companies to maintain transparency is mounting. As AI models become more integrated into daily life, the demand for accurate, evidence-based reporting on what these systems can and cannot do will only grow.
In conclusion, the incident underscores a vital lesson in the current era of AI development: the difference between a model that is "trained" and a model that is "intelligent" remains a chasm that marketing rhetoric has yet to bridge. While the capabilities of systems like PaLM are undoubtedly significant, they are the result of rigorous data engineering and statistical modeling, not the mysterious, autonomous sparks of a new life form. For the public, the takeaway is clear: when a technology is described as a "black box" that even its inventors don’t understand, it is often a sign to look closer at the data—and the motives—behind the curtain.