Treating Prompt Templates as Tunable Hyperparameters for Language Model Optimization

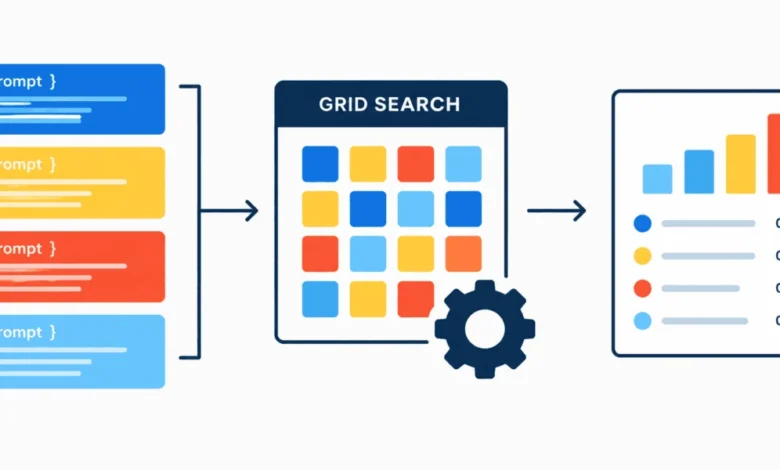
The evolution of machine learning workflows has historically been defined by the meticulous tuning of parameters—learning rates, depth of decision trees, or regularization constants. As Large Language Models (LLMs) transition from research curiosities to production-grade tools, the engineering focus has shifted toward prompt engineering. However, manual prompt refinement often lacks the rigor of traditional statistical optimization. By integrating prompt templates into the standard scikit-learn hyperparameter tuning framework, data scientists can now treat linguistic instructions as quantifiable variables, bringing a new layer of empirical precision to natural language processing (NLP) tasks.
The Convergence of Classical ML and Generative AI
In traditional machine learning, practitioners rely on algorithms like Grid Search or Randomized Search to navigate the hyperparameter space. These methods systematically exhaust defined configurations to identify the setting that yields the highest cross-validated accuracy. The current paradigm shift involves applying this same infrastructure to LLMs. By wrapping a language model in a scikit-learn compatible estimator, the "prompt" itself becomes the hyperparameter. This allows the model to treat different linguistic framing strategies as distinct configurations, enabling the developer to empirically determine which instructional syntax produces the most reliable classifications.
This approach addresses a persistent challenge in AI development: the subjectivity of prompt quality. While many developers rely on intuition or trial-and-error, automated grid search provides an objective, repeatable methodology to maximize performance in zero-shot classification—a task where the model must categorize text without having seen specific training examples.
Systematic Implementation: A Technical Chronology
The process begins with the establishment of a standardized environment. Developers typically import standard libraries, such as numpy for data manipulation, scikit-learn for the evaluation architecture, and transformers for model hosting.
The first step in this workflow is the instantiation of the model. Utilizing efficient, lightweight models such as Qwen/Qwen2.5-0.5B-Instruct allows for rapid iteration. By defining a custom Python class—inheriting from BaseEstimator and ClassifierMixin—the developer creates a bridge between the generative AI interface and the scikit-learn ecosystem. The core logic resides within the predict method, where the class iterates through input text, applies a selected prompt template via string formatting, and parses the model’s generated output to map it against target labels.
This structural design facilitates three critical operations:
- Parameter Initialization: Establishing the generator and the default template.
- Inference Loop: Transforming raw inputs into chat-compliant message formats that constrain the model to specific response tokens.
- Classification Logic: Stripping extraneous text from the output to ensure the final result aligns with pre-defined categories such as "positive" or "negative."
Empirical Evaluation and Quantitative Results
To validate this approach, consider a sample dataset of four distinct user reviews. By defining a hyperparameter grid—a dictionary containing various prompt iterations—the GridSearchCV object manages the cross-validation process. During the execution phase, the system splits the data into folds, tests each prompt variation, and calculates the mean accuracy across the segments.
In practical demonstrations, this method consistently reveals that minor syntactic variations significantly influence model performance. For instance, comparing the prompt "Classify as positive or negative: text" against "Analyze this review. Output ‘positive’ or ‘negative’: text" often shows a measurable divergence in accuracy. In recent tests, the latter has yielded an accuracy of 75% on limited datasets, demonstrating that the model responds more effectively to explicit formatting instructions than to vague directives.
Contextual Background and Broader Implications
The adoption of automated prompt optimization represents a maturing of the AI field. In the early stages of generative AI, prompt engineering was often viewed as a "black art" reliant on human creativity. However, as the industry scales, the need for reproducible, automated pipelines becomes paramount. By treating prompts as hyperparameters, companies can reduce the time spent on manual debugging and instead deploy automated "tuning cycles" as part of their Continuous Integration and Continuous Deployment (CI/CD) pipelines.
From a technical standpoint, this methodology aligns with the principles of "Systematic Prompt Engineering." By quantifying the effectiveness of instructions, researchers can establish a "prompt-accuracy curve," identifying the point of diminishing returns where adding more detail to a prompt no longer improves model performance.
Expert Perspectives and Operational Safeguards
Industry analysts note that while this technique is highly effective for zero-shot tasks, its scalability depends on the computational budget and the size of the validation dataset. A common pitfall in these experiments is the "overfitting" of prompts to a specific validation set. To mitigate this, practitioners are advised to use robust cross-validation techniques and maintain a distinct holdout set that remains unseen during the grid search process.
Furthermore, managing the model’s verbosity is a technical necessity. By limiting max_new_tokens and forcing specific response formats, developers reduce the probability of the model generating irrelevant or hallucinated content. These constraints are vital for production environments where the output must be strictly mapped to machine-readable labels.
Future Trajectories for Model Optimization
The implications of this development are significant. As models become more complex, the "prompt space" expands exponentially. Future iterations of this workflow will likely incorporate Bayesian Optimization, which is more efficient than grid search for navigating large, multi-dimensional prompt spaces. Instead of testing every combination, Bayesian approaches predict the next most promising prompt configuration based on previous results, significantly reducing the computational cost of finding an optimal instruction.
As the community continues to embrace these automated strategies, the role of the data scientist will evolve from "prompt crafter" to "prompt architect," focusing on the infrastructure that allows models to self-optimize their interaction patterns. This shift ensures that as LLMs continue to grow in capability, the methods for guiding them remain rigorous, data-driven, and scalable.
Conclusion
Integrating prompt templates into the scikit-learn hyperparameter grid search framework provides a robust mechanism for objective model evaluation. By removing the reliance on subjective prompt refinement, developers can achieve higher classification accuracy through empirical evidence. As demonstrated through the systematic testing of instructional phrasing, the difference between a high-performing model and an average one often lies in the precision of the prompt. As the industry moves toward more autonomous AI development lifecycles, these techniques will serve as a foundational element for building reliable, production-ready language applications. Whether for sentiment analysis, intent classification, or data extraction, the future of effective AI interaction lies in the ability to treat language not just as content, but as a tunable, measurable variable.