A Gentle Introduction to Model Distillation and the Escalating Industry Conflict

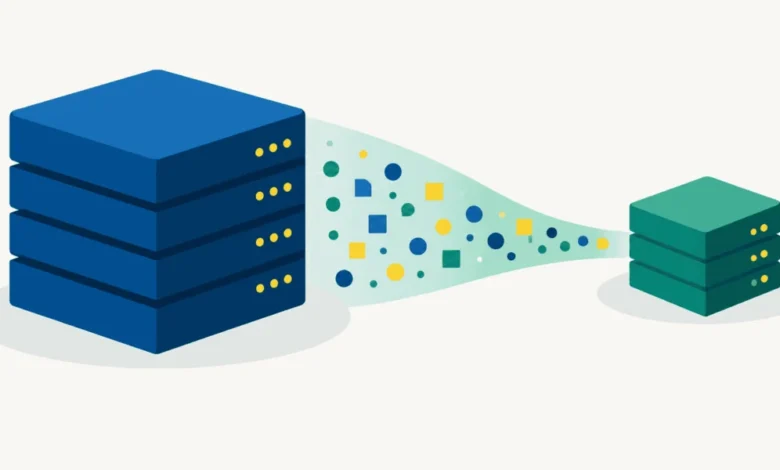
The global race to develop the most powerful artificial intelligence models has shifted from a pure focus on sheer parameter count to a new, more contentious frontier: model distillation. At its core, distillation is a sophisticated engineering technique designed to shrink massive, resource-intensive models—such as GPT-4, Gemini, and Claude—into compact, efficient versions capable of running on consumer hardware like smartphones and laptops. While the process has been a staple of machine learning research for a decade, its recent application has sparked a geopolitical and commercial firestorm, as major AI labs allege that rivals are systematically "harvesting" their proprietary knowledge to build competing models at a fraction of the development cost.
Understanding the Mechanics of Knowledge Transfer
To grasp the implications of modern distillation, one must first understand how models learn. In traditional machine learning, a model is trained on "hard labels"—a binary approach where an image is categorized as either a dog or a cat. This method is inherently reductive, discarding the nuanced relationships between objects. A model trained on hard labels ignores the "dark knowledge"—a term coined by pioneer Geoffrey Hinton—that represents the subtle correlations between classes. For example, a model might identify an image as a dog, but its internal probability distribution might also reveal that the image shares features with a wolf, while having nothing in common with a car.
Classical distillation captures this dark knowledge by training a smaller "student" model to replicate the full probability output of a larger "teacher" model. By using a process known as "temperature scaling," researchers can soften the teacher’s output, making the subtle relationships between categories visible to the student. This allows the student to learn not just the correct answer, but the teacher’s underlying reasoning process, effectively compressing the intelligence of a multi-billion parameter system into a much leaner architecture.
The Evolution Toward Large Language Models
The transition from image classification to Large Language Models (LLMs) necessitated a shift in methodology. Because LLMs generate text token-by-token across vast vocabularies, the classical logit-based approach has been supplemented by synthetic data distillation. In this paradigm, a teacher model generates high-quality reasoning chains, code snippets, and structured analysis. A student model is then fine-tuned on this synthetic dataset. This method is particularly potent because it requires only API access to the teacher’s output, bypassing the need for access to the internal weights or architecture of the original model.
This shift has created a significant divide between legitimate internal optimization and unauthorized external harvesting. Within organizations, feature distillation—where the student learns from the intermediate activation patterns of the teacher—remains a standard tool for creating specialized, cost-effective models. However, when this technique is applied across company lines without authorization, it transforms from a benign optimization task into an existential threat to intellectual property.
A Chronology of the 2026 Distillation Crisis
The year 2026 marked a turning point in the industry’s tolerance for these practices. The following timeline captures the rapid escalation of the conflict:
- January 2026: Reports emerge from cybersecurity firms regarding "distillation attacks," where automated agents are programmed to interact with public APIs to extract reasoning patterns from leading LLMs.
- March 2026: OpenAI files a formal memo with the US House Select Committee on China, asserting that specific foreign entities are utilizing third-party routing and obfuscation to "scrape" the latent intelligence of GPT-4.
- April 2026: During legal proceedings, Elon Musk confirms that xAI utilized outputs from OpenAI’s models to assist in the training of Grok, highlighting that the practice of "knowledge distillation" is viewed by some as an industry standard rather than theft.
- June 2026: Anthropic releases a technical breakdown alleging that Alibaba’s Qwen laboratory orchestrated a campaign using 25,000 fake accounts to generate over 28 million interactions with Claude, specifically targeting its agentic reasoning capabilities.
- July 2026: Google’s Threat Intelligence Group identifies a sophisticated operation involving over 100,000 prompts designed to map the decision-making boundaries of the Gemini model.
The Economic Implications of Synthetic Harvesting
The economic impact of these activities is difficult to quantify but potentially staggering. The development of a frontier model requires hundreds of millions of dollars in compute, massive energy expenditures, and years of specialized research. If a competitor can "distill" that capability by paying only for API usage, they effectively externalize the massive R&D costs of the primary developer.
Consider the case of DeepSeek. While their technical reports cite training costs in the low single-digit millions of dollars, independent analysts from SemiAnalysis have suggested that the total investment, including underlying research and infrastructure, likely exceeds $1 billion. If unauthorized distillation is being used to bridge the gap between "first-mover" models and "fast-follower" models, the competitive landscape of the AI industry may be fundamentally tilted. This creates a "free-rider" problem that discourages the massive, risky investments required to push the boundaries of AI, as the primary beneficiary of the innovation may not be the party that funded it.
Official Responses and Industry Defenses
The response from the accused parties has been largely dismissive. Alibaba and other firms implicated in the 2026 reports have denied systematic harvesting, often framing their activities as standard fine-tuning practices or public benchmarking. Because the legal framework governing AI outputs remains in its infancy, these disputes rarely reach a courtroom. Current US copyright law generally does not protect the raw output of an AI model, leaving labs to rely on Terms of Service (ToS) agreements—a fragile defense against international entities that may not be subject to the same legal jurisdictions.
In response to these challenges, a "defensive coalition" has begun to form. Leading labs like OpenAI, Anthropic, and Google are reportedly sharing threat intelligence to identify and block accounts engaged in high-volume, repetitive prompting. They are also experimenting with defensive measures such as "output watermarking" to identify synthetic data, and anomaly detection algorithms designed to spot the distinct, non-human-like patterns of an automated student model querying a teacher.
Structural Challenges and Future Outlook
The fundamental tension between openness and protection remains unresolved. To foster a healthy ecosystem, AI companies want to provide public access to their models, which requires an API. However, that same API provides the "data stream" necessary for a competitor to build a rival model.
If the industry moves toward stricter rate limiting, it will inevitably degrade the experience for legitimate researchers, developers, and hobbyists. If they move toward mandatory authentication or invasive user-tracking to prevent distillation, they risk alienating the user base that drives model adoption.
The most likely outcome is a dual-track future. Large labs will continue to advocate for legislative changes that create a new category of "model intellectual property" while simultaneously building more robust, AI-driven firewalls to detect and thwart automated harvesting. Meanwhile, the open-source community will likely continue to thrive on the back of legitimately licensed distillation—such as Meta’s Llama 3.1, which encourages developers to use its outputs for training smaller variants.
Ultimately, model distillation is a testament to the efficiency of neural networks. It proves that the "intelligence" of a model is not just in its weight count, but in the structural information it encodes. As the cost of training models continues to climb, the ability to effectively transfer this knowledge—and the ability to protect it—will define the winners and losers of the next decade of artificial intelligence. The current controversy is not merely a legal or ethical dispute; it is a structural adjustment to a world where intelligence can be copied, compressed, and redeployed at near-zero marginal cost.
Related posts: