Transforming Open-Weight Language Models into High-Performance Decision Engines via Unsloth and Qwen3.5

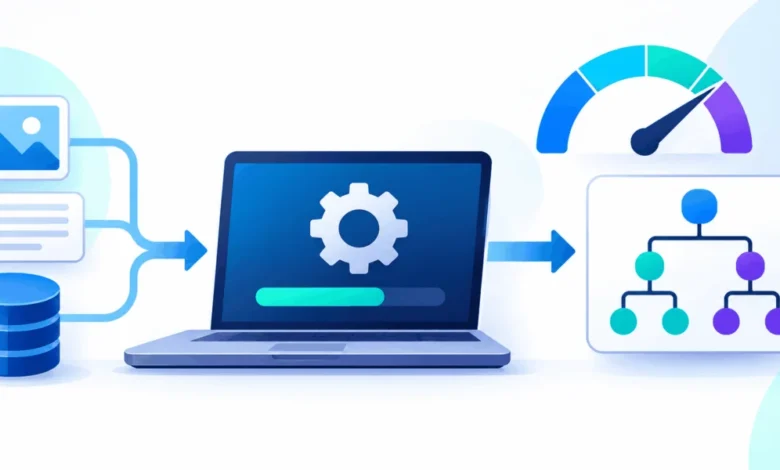
The shift from generative artificial intelligence to deterministic decision-making represents a significant evolution in machine learning architecture. Rather than relying on the verbose, probabilistic text generation associated with traditional Large Language Models (LLMs), developers are increasingly turning toward "decision models"—specialized systems engineered to perform intent classification, request routing, and structured data extraction with high precision and low latency. By leveraging the Unsloth framework to fine-tune open-weight models like Qwen3.5-4B, practitioners can now bypass the resource-heavy overhead of standard text generation, replacing it with a streamlined decision head that outputs actionable structured data.
The Rise of Structured Decision Models
For years, the industry standard for NLP tasks—such as intent detection—involved complex pipelines or prompt-engineered LLMs that were often prone to "hallucinations" or unnecessary verbosity. When a user asks, "Can you help me check the balance in my savings account?" a standard LLM might produce a paragraph explaining the banking process. In contrast, a decision model is trained to recognize the semantic core of the request and return a JSON object: "intent": "balance", "confidence": 0.97.
This transition marks a departure from the "chatbot" paradigm toward an "agentic" paradigm. Models such as Jev, Laya, and Clef have popularized the use of decision heads that process inputs and select from a predefined list of possibilities. This methodology is particularly vital for industrial applications, including automated content moderation, sentiment-based ticket routing, and autonomous agent workflows, where the accuracy of a classification is significantly more valuable than the creativity of a prose response.
Technical Foundations: Unsloth and Qwen3.5
The technical feasibility of this approach has been greatly enhanced by the Unsloth framework, which optimizes memory usage and training speed for fine-tuning operations. By using 4-bit LoRA (Low-Rank Adaptation) quantization, engineers can now train sophisticated models on hardware as accessible as a Google Colab instance equipped with a standard NVIDIA Tesla T4 GPU.
The Qwen3.5-4B architecture serves as an ideal base for this implementation. Its lightweight footprint allows for rapid iteration without sacrificing the linguistic nuance required to understand diverse user inputs. When paired with Unsloth’s FastDecisionModel, the base LLM acts as the "reasoning engine," while the newly added decision head manages the categorization process. This head evaluates the input against a fixed set of criteria, assigning probability scores to each available option.
Implementing the CLINC150 Intent Classifier
To demonstrate the efficacy of this architecture, researchers utilized the CLINC150 dataset, a comprehensive benchmark designed specifically for intent detection and out-of-scope request identification. The dataset covers 150 distinct intent categories across diverse domains, including personal finance, travel, and logistics.
The workflow for building this model follows a structured, multi-stage pipeline:
- Environment Setup: The initial phase requires the installation of optimized kernels via the Unsloth library. This ensures that the training process utilizes the most efficient GPU pathways, reducing the typical training time by nearly half compared to traditional PyTorch implementations.
- Model Initialization: Unlike standard LLM loaders, the
FastDecisionModel.from_pretrainedfunction is used to initialize the model with a specialized output layer. This layer is calibrated to handle "Choice" type questions, where the output space is strictly defined by the developer. - Data Preprocessing: The CLINC150 dataset must be converted into a format compatible with decision-making. This involves mapping natural language queries to their corresponding intent labels. For a pilot study, ten representative intents were selected, including "calories," "payday," and "time," to measure baseline performance.
- Parameter-Efficient Fine-Tuning (PEFT): By utilizing LoRA with a rank of 16, developers can fine-tune roughly 2% of the model’s total parameters. This maintains the core linguistic knowledge of the Qwen model while allowing the decision head to adapt specifically to the intent-classification task.
Performance Analysis and Statistical Gains
The results of such fine-tuning are quantifiable and stark. Before training, a randomized decision head typically performs at the level of random chance—roughly 10% accuracy for a 10-class task. Upon completion of 60 training steps, the model exhibited a dramatic shift in performance.
In empirical testing, validation accuracy surged from 18.5% to 100% on the controlled subset of the CLINC150 data. Furthermore, the Expected Calibration Error (ECE)—a critical metric for measuring the reliability of confidence scores—dropped significantly. A lower ECE indicates that when the model reports a 95% confidence in its classification, it is indeed correct 95% of the time, a level of calibration rarely achieved by off-the-shelf generative models.
Broader Implications for Enterprise AI
The ability to deploy high-accuracy decision models on open-weight architecture has profound implications for enterprise software. Organizations that were previously hesitant to adopt LLMs due to latency, cost, and unpredictability can now implement "decision-first" systems.
- Predictability: By forcing the model to select from a predefined list of intents, developers eliminate the risks associated with non-deterministic text generation.
- Cost-Efficiency: Because these models do not need to generate long sequences of tokens, the computational cost per request is reduced by several orders of magnitude compared to traditional LLM inference.
- Auditability: Structured JSON outputs are inherently easier to log, monitor, and analyze, making it simpler for organizations to maintain compliance and debug failure points in their AI pipelines.
Future Outlook and Limitations
While the results of this implementation are promising, the transition to decision models is not without challenges. The primary hurdle remains the generalization of the model to "out-of-scope" queries. As demonstrated in the evaluation, the model excels when the input falls within the trained intent space. However, real-world deployment requires robust mechanisms to detect when a user query does not match any of the predefined intents.
The industry is currently moving toward a hybrid approach, where a small, fast decision model handles the primary routing and classification, while a larger, generative model is only invoked if the decision model reports a low confidence score or if the user requires a conversational follow-up. This "cascade" architecture represents the most likely future for large-scale AI deployment.
In summary, the integration of Unsloth and Qwen3.5 demonstrates that the future of language modeling is not merely in generating text, but in making precise, verifiable, and highly efficient decisions. As these frameworks continue to mature, the barriers to entry for custom-built, enterprise-grade intent classifiers will continue to collapse, enabling a new wave of highly responsive, reliable, and intelligent automated systems.