Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head

The rapid proliferation of large language models (LLMs) has fundamentally altered the landscape of natural language processing (NLP). As organizations look to transition from general-purpose AI applications to specialized, domain-specific implementations, they are frequently confronted with a critical architectural decision: should they perform a full or parameter-efficient fine-tuning of the model, or should they leverage the model as a static feature extractor? This choice has significant downstream implications for computational overhead, latency, and model precision.
The Evolution of Model Adaptation
Historically, the machine learning community favored full model fine-tuning—the process of updating all weights in a pre-trained neural network to optimize performance on a specific dataset. However, as model parameters have scaled from millions to hundreds of billions, full fine-tuning has become prohibitively expensive for most enterprises.
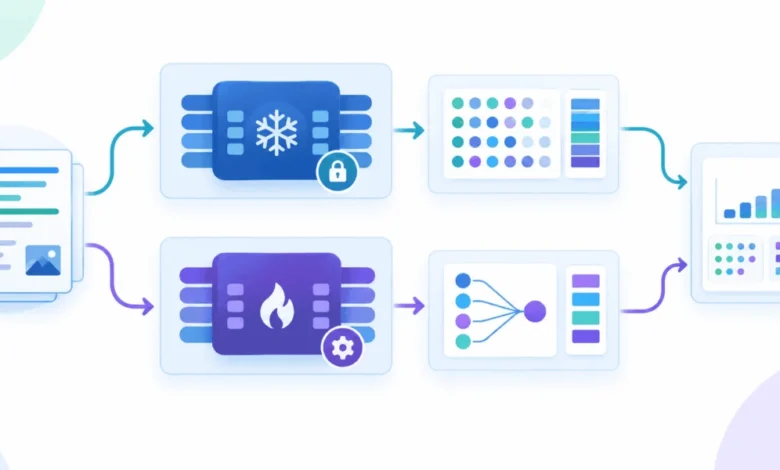
The emergence of Low-Rank Adaptation (LoRA) and its 4-bit quantized variant (QLoRA) has provided a middle ground. By freezing the original backbone of the LLM and training only small, low-rank adapter matrices, developers can achieve performance gains comparable to full fine-tuning while reducing memory requirements by up to 90%. Simultaneously, the "frozen embedding" approach—where an LLM acts as a fixed encoder that feeds representations into a traditional classifier like a Random Forest or Support Vector Machine (SVM)—has seen a resurgence due to its efficiency and simplicity.
Comparative Performance Metrics
In a controlled experiment using the AG News dataset—a corpus comprising 120,000 news articles categorized into four distinct classes—researchers compared the two methodologies. Utilizing the Qwen2.5-1.5B model as the base architecture, the comparison focused on two primary metrics: total training duration and final classification accuracy.
The frozen embedding strategy, where the model’s last hidden state was extracted via mean pooling and passed to a Scikit-Learn Random Forest classifier, resulted in an accuracy of 82.0%. While the feature extraction phase was computationally intensive—taking approximately 96.5 seconds on a T4 GPU—the training phase for the Random Forest was nearly instantaneous at 2.8 seconds.
Conversely, the QLoRA fine-tuning approach yielded an accuracy of 87.0%. While this 5% performance boost is significant for high-stakes applications, it required 300.3 seconds of GPU time. This data suggests that while fine-tuning provides superior accuracy, it does so at a cost of roughly three times the compute time for a small-scale dataset. For massive datasets, this time disparity often compounds, leading to significantly higher cloud infrastructure costs.
Technical Chronology and Implementation
The implementation of these strategies follows distinct technical paths. The frozen embedding approach relies on the transformer’s ability to act as a universal feature vector generator. By disabling gradient calculations (via torch.no_grad()), developers can convert raw text into dense, high-dimensional vectors. These vectors serve as stable, static inputs for classical machine learning algorithms, which are often more robust to noise and less prone to the "catastrophic forgetting" that can occasionally plague fine-tuned LLMs.
In contrast, the LoRA methodology requires the injection of trainable adapters into specific modules, such as the q_proj and v_proj layers of the attention mechanism. This process is inherently iterative. During the training loop, the Trainer object manages weight updates specifically within the adapter matrices, leaving the base model’s pre-trained weights undisturbed. This preserves the general knowledge of the model while allowing it to specialize in the nuances of the target domain.
Industry Implications and Strategic Selection
The choice between these two strategies is rarely a matter of objective "superiority" but rather a alignment with project-specific constraints. Industry analysts suggest a framework for decision-making based on the "Three C’s": Context, Cost, and Capability.
- Context (Generative vs. Discriminative): For generative tasks—such as drafting technical reports, generating code, or creative writing—fine-tuning is almost universally required. A frozen embedding approach is purely discriminative and cannot alter the model’s output generation style or factual grounding.
- Cost (Infrastructure Constraints): In resource-constrained environments, such as edge computing or free-tier cloud instances, the frozen embedding approach is often the only viable path. It eliminates the need for complex training loops and expensive gradient memory allocation.
- Capability (Precision Requirements): If the application requires maximum possible accuracy, such as in legal document classification or medical diagnostic triaging, the 5% accuracy gain observed in the QLoRA approach is often worth the extra computational expenditure.
Expert Perspectives on Model Stability
Data scientists often point out that frozen embeddings provide a layer of interpretability that fine-tuned LLMs lack. Because the final decision-making layer is a traditional algorithm like a Random Forest or Logistic Regression, stakeholders can analyze feature importance—identifying which tokens or linguistic patterns are driving specific classifications.
"The temptation is always to fine-tune because it feels like the more ‘advanced’ solution," says a lead engineer at a prominent AI research firm. "But in production, stability is king. If you can achieve 82% accuracy with a frozen backbone and a simple classifier, you have a system that is easy to monitor, version, and debug. You only move to fine-tuning when that baseline fails to meet your business KPIs."
Broader Impact and Future Outlook
As the AI field matures, the trend is shifting toward "modular intelligence." Instead of monolithic models that handle every task, companies are building architectures where a frozen, high-performance base model serves as an "encoder," while specialized, lightweight adapters are swapped in and out based on the specific classification task.
This shift has implications for the "AI divide." Organizations with limited budgets are finding that they do not necessarily need to train a foundation model from scratch or even perform exhaustive fine-tuning to remain competitive. By effectively leveraging the frozen weights of open-weights models like Qwen, Llama, or Mistral, developers can build highly effective, domain-specific systems that operate on a fraction of the compute resources previously thought necessary.
Ultimately, the decision between fine-tuning and frozen embeddings is a microcosm of the broader challenge in the AI era: balancing the raw power of large-scale models with the practical, economic, and operational realities of real-world deployment. As tools for both methods become more refined, the emphasis will continue to move toward automated pipelines that can evaluate both strategies and select the most efficient one based on the specific characteristics of the incoming data.